
Alpha158 Enhanced plugin
English · 简体中文 · Plugin management
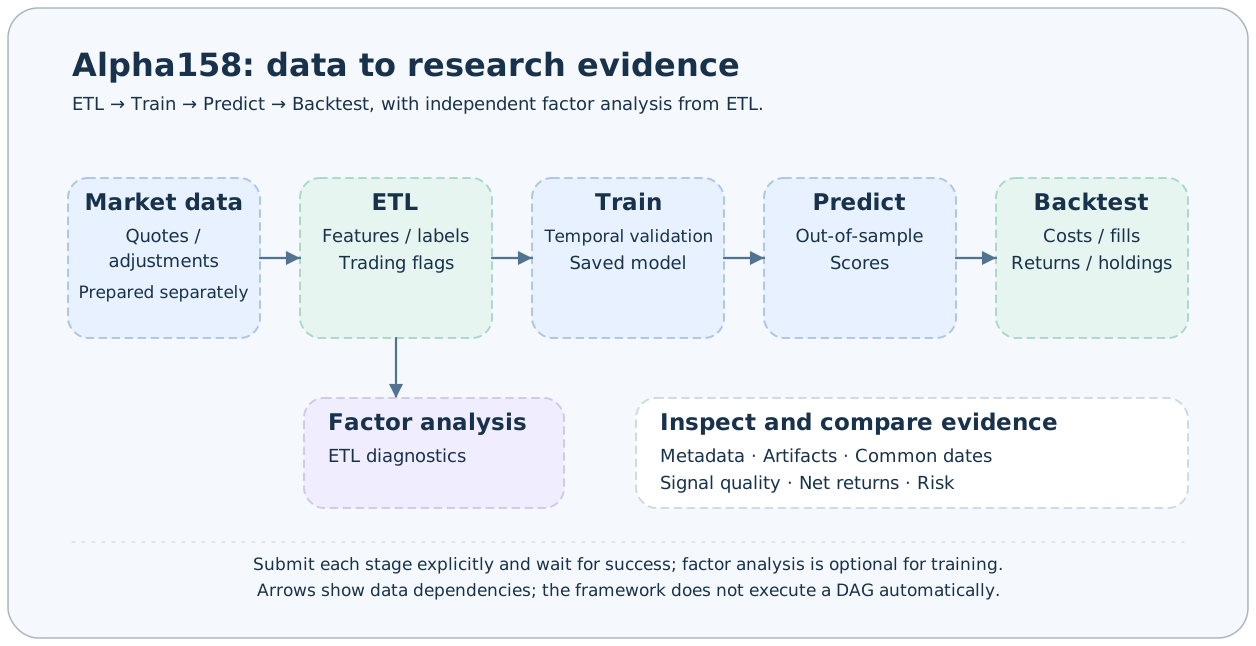
An independent AxonX research plugin for data processing, factor analysis, LightGBM training, out-of-sample prediction, and TopN backtesting.
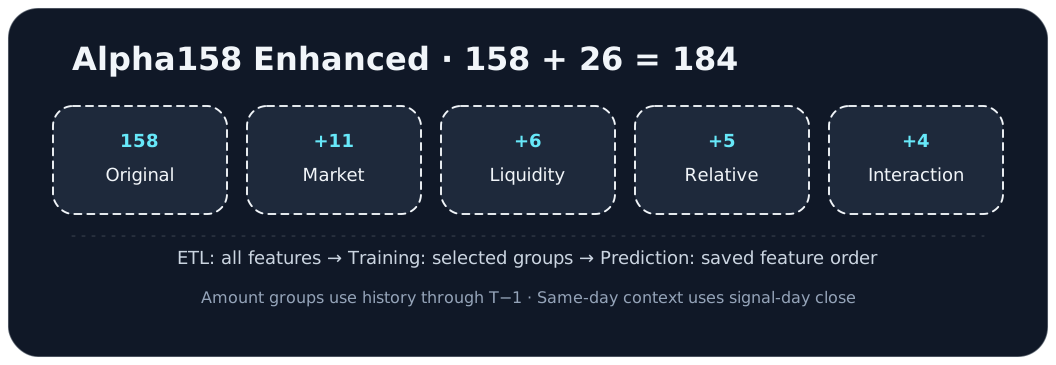
The enhanced plugin preserves the original 158 features and adds 26 market, traded-amount group, relative-performance, and interaction features, for 184 in total. It includes its own implementation and does not depend on the original plugin package. Traded amount measures activity, not market capitalization.
Install and inspect
Requires Python 3.12+; local Task execution supports macOS and Linux. Install into the execution service’s Python environment, then restart the service to reload contributions. LightGBM, NumPy, and Polars are installed as dependencies.
pip install axonx-alpha158-enhanced
axonx plugin list
axonx plugin show axonx-alpha158-enhanced
For source development, run from the repository root:
pip install -e ./plugins/a158_enhanced
axonx plugin inspect ./plugins/a158_enhanced
The local CLI environment may differ from the remote service environment. For remote deployment, configure the target service token and specify the target explicitly:
export AXONX_TARGET_TOKEN='<service token>'
axonx plugin install ./plugins/a158_enhanced --target 'http://<host>:1024'
axonx plugin list --target 'http://<host>:1024'
Restart the target service as indicated by restart_required, then query Task definitions. See plugin management.
Prepare data
Configure AXONX_TUSHARE_TOKEN in the execution service environment and use the built-in download_tushare_task to prepare Tushare Parquet data. The default ETL input is tushare/ inside the workspace, rather than the current shell directory.
axonx submit --task download_tushare_task \
  --start-date 20140101 --end-date 20260930 \
  --datasets 'static,stk_limit,daily,adj_factor,index_weight'
Save the returned task_id and run_id, and wait for the download to succeed before submitting ETL:
axonx --client-timeout 86400 wait_task \
--task-id '<download_task_id>' --run-id '<download_run_id>'| Files | Purpose |
|---|---|
*/*/daily.parquet, */*/adj_factor.parquet | Required market data and adjustment factors |
trade_cal.parquet, stock_basic.parquet, namechange.parquet | Required trading calendar, stock master data, and historical names |
*/*/stk_limit.parquet | Official price limits used for tradability |
*/*/index_weight.parquet | CSI 300 weights used for index pools and benchmarks |
Prepare sufficient preceding history for rolling windows. The example trains from 2015, so downloads start in 2014. The default download only looks back seven calendar days and does not provide a full history. For credentials, partition layout, and updates, see Tushare downloads.
Tasks and execution
| Task | Upstream | Outputs |
|---|---|---|
a158e_etl | Workspace market data | Features, labels, trading status, and statistics |
a158e_factor | ETL Task ID | Factor diagnostics and analysis |
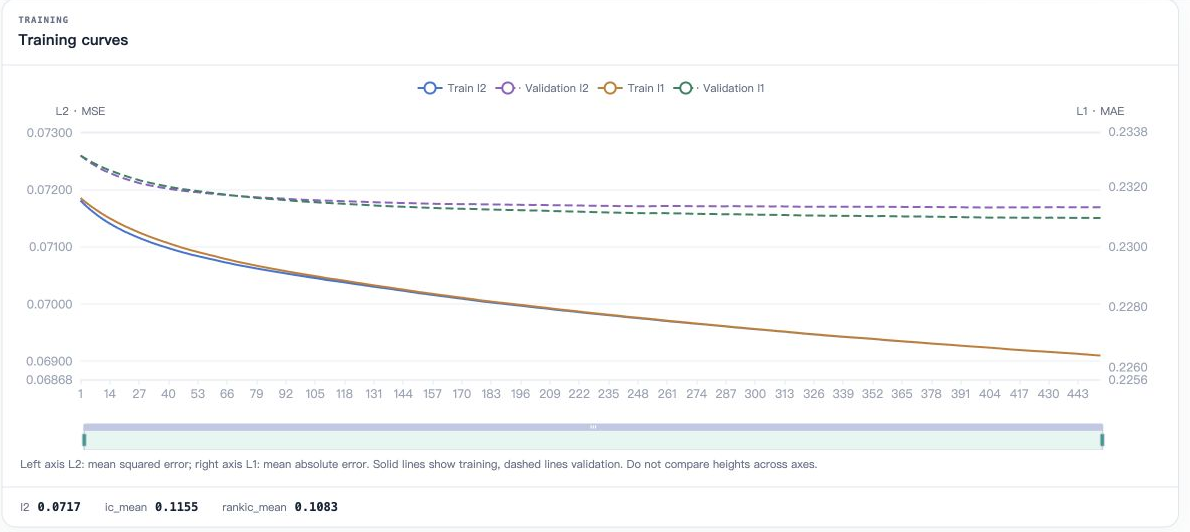
a158e_train | ETL Task ID | Model, training protocol, validation curves, and feature importance |
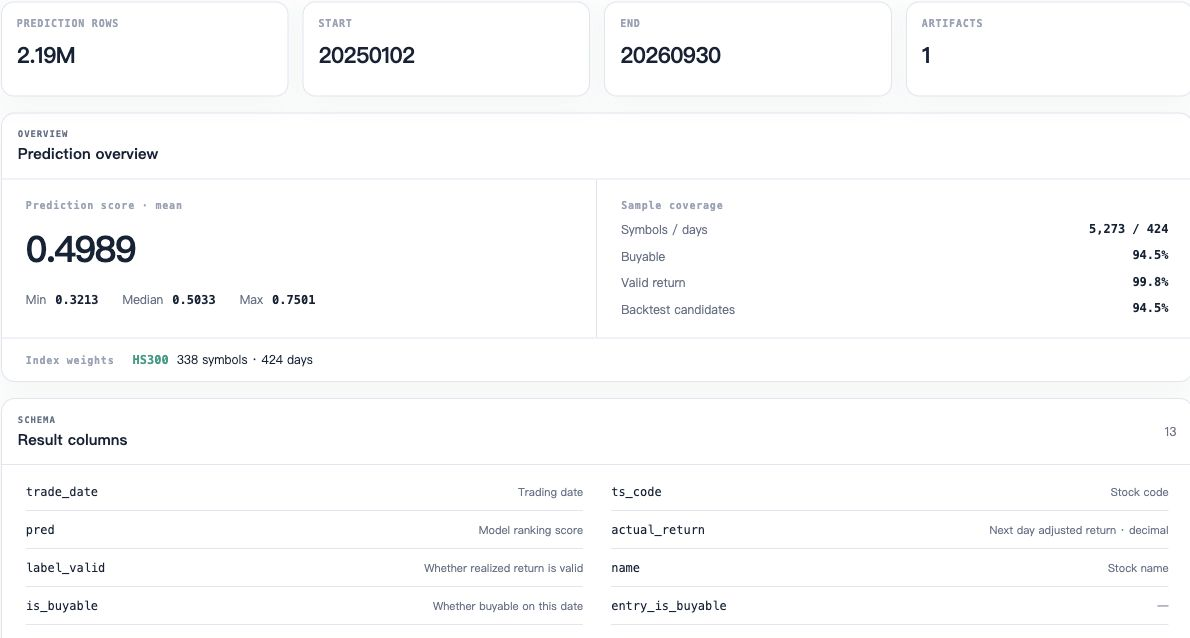
a158e_predict | Train Task ID | Full-cross-section predictions and statistics |
a158e_backtest | Predict Task ID | Daily backtests, period summaries, and holding-related artifacts |
Factor analysis branches from ETL and is not a prerequisite for training. Submit in the following order, use the actual returned Task IDs, and wait for each stage to succeed before submitting its downstream stage.
axonx submit --task a158e_etl --start-date 20150101 --end-date 20260930

# After ETL succeeds
axonx submit --task a158e_factor --source-tasks '<etl_task_id>'
axonx submit --task a158e_train --source-tasks '<etl_task_id>' \
  --train-start 20150101 --train-end 20230101 \
  --context-groups market,liquidity,relative,interaction

# After training succeeds
axonx submit --task a158e_predict --source-tasks '<train_task_id>' \
  --pred-start 20230101 --pred-end 20260930

# After prediction succeeds
axonx submit --task a158e_backtest --source-tasks '<predict_task_id>'
For every wait, provide both identifiers from that submission:
axonx --client-timeout 86400 wait_task \
  --task-id '<task_id>' --run-id '<run_id>'
axonx get_task_definition --task a158e_train
For remote execution, add the same --target to all submission, wait, and definition queries. Install and execute against the same service environment.
Key parameters
| Stage / parameter | Default | Meaning |
|---|---|---|
ETL start_date / end_date | 20140101 / null | First / last output dates, inclusive |
ETL min_history_coverage | 0.8 | Minimum history coverage for rolling features |
Train train_start / train_end | 20150101 / 20230101 | Inclusive start, exclusive cutoff |
Train label_column | label_1d_rank | Daily cross-sectional return rank target |
Train trim_tail | 0.025 | Remove 2.5% of raw returns from each daily tail |
Train validation_ratio | 0.10 | Last training dates reserved for internal validation |
Train num_boost_round / early_stopping_rounds | 1000 / 50 | Maximum rounds / early stopping patience |
Train random_seed | 42 | Model sampling seed |
Predict pred_start / pred_end | 20230101 / null | Prediction interval; start must not precede the training cutoff |
Backtest transaction_cost_rate | 0.002 | Transaction cost multiplied by actual daily turnover |
Backtest annualization_days | 252 | Trading days used for annualization |
Consult get_task_definition in the execution environment for the complete parameter Schema.
Features, labels, and backtest protocol
Original features use the f_alpha158_* namespace: 13 current-day price features and 29 rolling feature families over 5, 10, 20, 30, and 60 trading-day windows. Prices are adjusted, and trading-calendar and listing-status information are preserved.
The normal label is adjusted close-to-close return from signal day T to T+1. If the planned exit is unavailable, exit is delayed until the first sellable date. Training, factor evaluation, and signal ranking metrics use valid, undelayed one-day samples. Prediction retains the full cross section without filtering stocks by future labels.
Backtesting ranks same-day signals and simulates buying at the same-day close using daily tradability proxies. It does not model after-close queuing or partial fills. Positions retain capital until actual exit; open positions remain at cost, and net returns are booked on realized exits. Top30 holding details describe signal targets, rather than the live position book.
For return, cost, IC, and holding definitions, see Interpreting backtests.
Inspect results in Studio
Inspect parameters, logs, metadata, and upstream relationships in Task details. Research result pages display ETL, factor, training, prediction, and backtest artifacts. The screenshots below illustrate existing experiments and do not represent every run of this plugin.
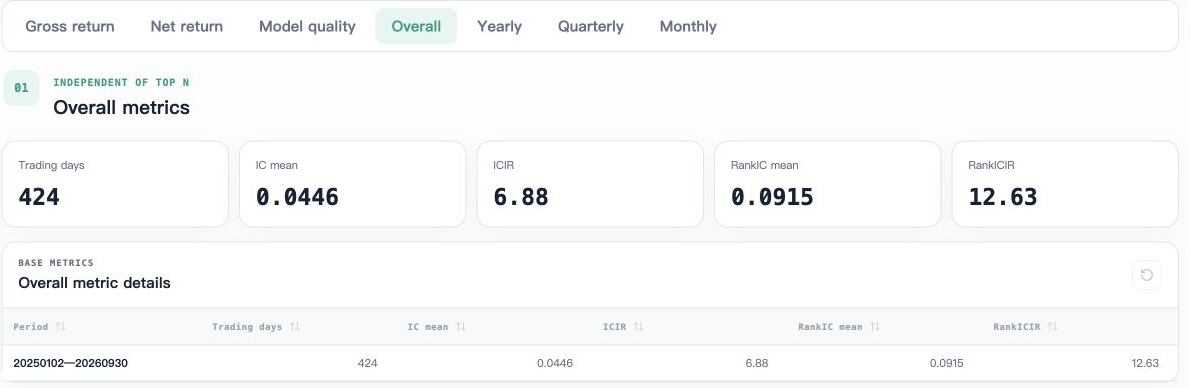
Troubleshooting and source
| Problem | Check |
|---|---|
| Missing registered Task | Installation environment, entry point, service restart, and target machine |
| ETL missing data | Workspace Tushare partitions, three static files, and historical date coverage |
| Prediction date error | pred_start must not precede train_end; model and ETL metadata must be complete |
| Results differ from examples | Data snapshot, feature groups, dates, labels, parameters, and costs |
Task registration · ETL · Factor analysis · Training · Prediction · Backtesting
Research workflow · Research results · Task management
Feature groups
context_groups group | Added features | Content |
|---|---|---|
market | 11 | Market mean/median returns, advance ratio, return IQR, price-limit ratios, 5/20-day trends, standardized shock, activity, and amount concentration |
liquidity | 6 | Amount rank through T−1, stock activity, low/high amount-group returns, group spread, and its 5-day mean |
relative | 5 | Returns relative to market and amount group, daily return rank, and 5/20-day relative trends |
interaction | 4 | Market shock/downside × relative return, group spread × amount rank, and market activity × stock activity |
Enhanced ETL creates all 184 features. Training selects groups with --context-groups: none uses 158; market uses 169; market,liquidity,relative uses 180; all four use 184. Original names remain f_alpha158_*, and added names use f_context_*. Prediction follows the feature order saved in training metadata.
Group assignments use historical amount through T−1; same-day context is available after the signal-day close. Returns use adjacent trading-day adjusted closes; missing quotes do not turn returns across a suspension into one-day returns. The statistical pool is independent of future labels and buyability. Exact feature names and timing rules are in cross_section.py, and ETL metadata records context.feature_groups and the timing protocol.
Version and experiment findings
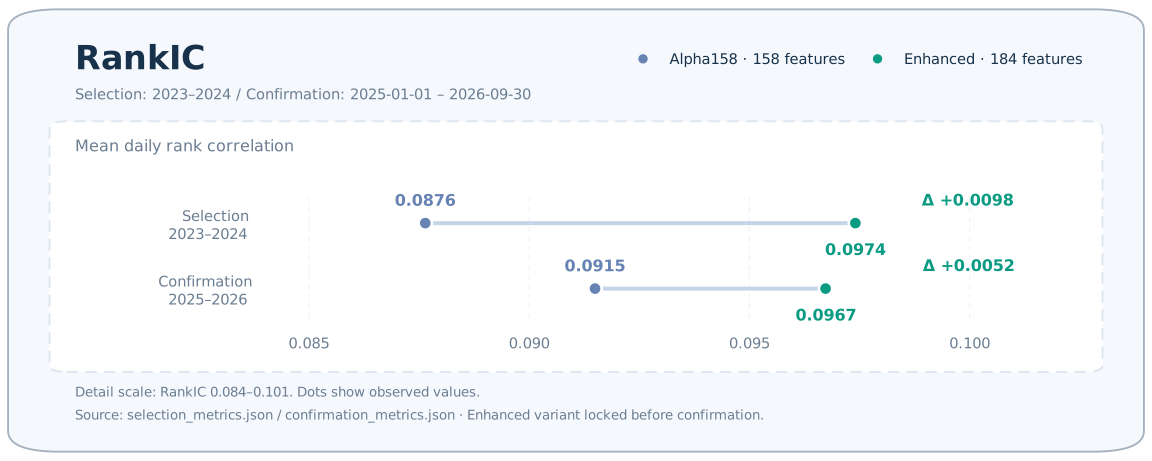
Version 0.1.2 enables all four groups by default, matching the locked 184-feature experiment. Training used 2015 through 2022; selection used 2023–2024; final confirmation used 2025-01-01 through 2026-09-30.
| Confirmation metric | Baseline | All groups |
|---|---|---|
| RankIC | 0.0915 | 0.0967 |
| Top10 net annualized return | −5.74% | 28.21% |
| Top20 net annualized return | −3.24% | 24.93% |
RankIC and Top10/20 net annualized returns improved in this data snapshot. Top1–3 returns declined. The 95% block-bootstrap intervals for all three paired daily increments cross zero in confirmation. Feature gain measures model use, rather than independent causal contribution.
Signal quality
TopN portfolio results
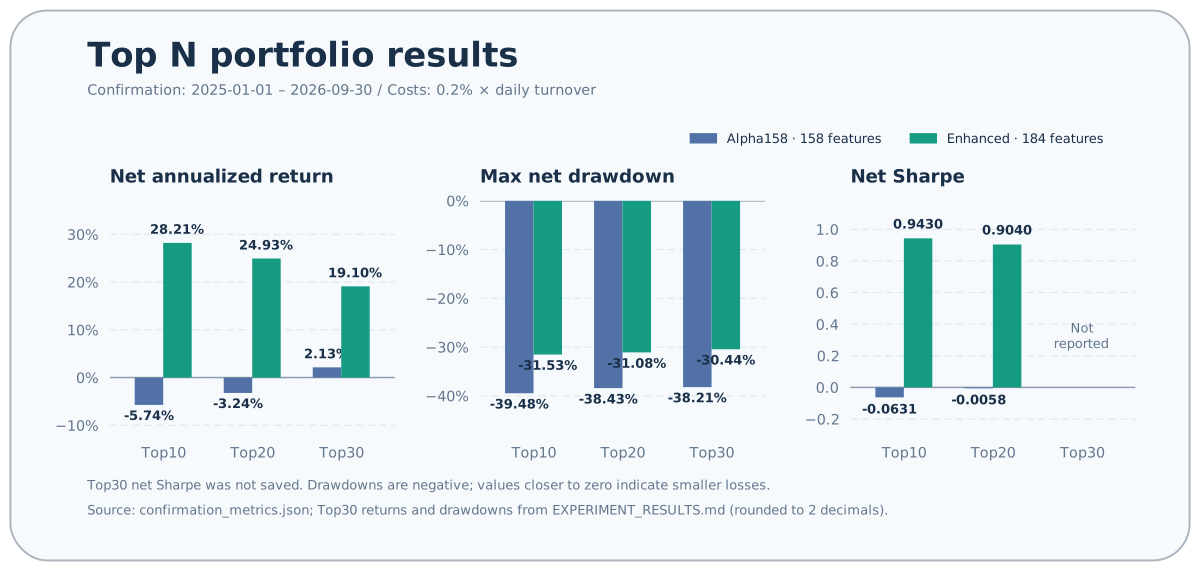
Net Sharpe is calculated from daily net returns after costs; Top30 net Sharpe was not saved. These charts summarize the historical experiment above, not expected performance on new data.
Experiment documents and evidence
The detailed historical documents are in Chinese; this English README provides the usage, protocol, findings, and reproduction entry points.
| Document | Purpose |
|---|---|
| Development plan | Research goals, timing, candidate features, controlled variables, selection and confirmation rules |
| Experiment process | Implementation, checks, corrections, execution times, Task/Run IDs, locked scheme, installation |
| Experiment results | Ablations, all TopN portfolios, yearly and regime metrics, paired intervals, importance, limitations |
| Evidence index | Committed metrics and validation summaries |
Evidence includes baseline parity, feature coverage, training parameters, selection metrics, selection decision, confirmation metrics, paired diagnostics, regime metrics, and feature importance.
Full submission responses, statuses, raw logs, daily Parquet files, and superseded runs remain in a local archive and are not committed. The process document records their purpose, identifiers, and corrections. Create new execution records for new experiments; do not reuse historical Task handles.
Reproduce the experiment
Install remotely using the deployment commands above. Prepare data matching the plan and record a fixed snapshot. Submit one enhanced ETL from 2015 onward, then train four independent models from that same ETL with none, market, market,liquidity,relative, and market,liquidity,relative,interaction. Keep the training period, model parameters, fee 0.002, and seed 42 fixed.
axonx submit --task a158e_train --source-tasks '<etl_task_id>' \
  --context-groups none --train-start 20150101 --train-end 20230101 \
  --target 'http://<host>:1024'

# Repeat training for each candidate group set, then wait for each model.
axonx submit --task a158e_predict --source-tasks '<train_task_id>' \
  --pred-start 20230101 --pred-end 20241231 --target 'http://<host>:1024'
# Wait for prediction before backtesting.
axonx submit --task a158e_backtest --source-tasks '<predict_task_id>' \
  --target 'http://<host>:1024'
Apply the plan’s selection rules and lock the chosen groups before confirmation. Predict only the baseline and locked model with --pred-start 20250101 --pred-end 20260930, wait, and backtest each prediction. Save configurations, model artifacts, predictions, backtest summaries, and daily outputs. Report experiments on different data snapshots separately. Local recovery/report scripts tied to the historical service are not committed.
Net Sharpe in the experiment report is calculated from daily net returns after costs and daily risk-free return; it differs from gross Sharpe in the original backtest output. The close-price execution proxy, delayed exits, and cost-based accounting for open holdings remain part of the protocol.
Local validation
From the repository root, after installing development dependencies:
PYTHONPATH=plugins/a158_enhanced .venv/bin/python -m pytest \
  plugins/a158_enhanced/tests/test_cross_section.py \
  tests/unit/test_alpha158_labels.py tests/unit/test_alpha158_backtest.py -q
Tests cover future-data causality, original feature contracts, historical grouping, suspension, flat returns, insufficient history, and independence of the statistical pool from labels and buyability.